Claude Leads 26% of Anthropic's AI R&D, Up From 1% in March
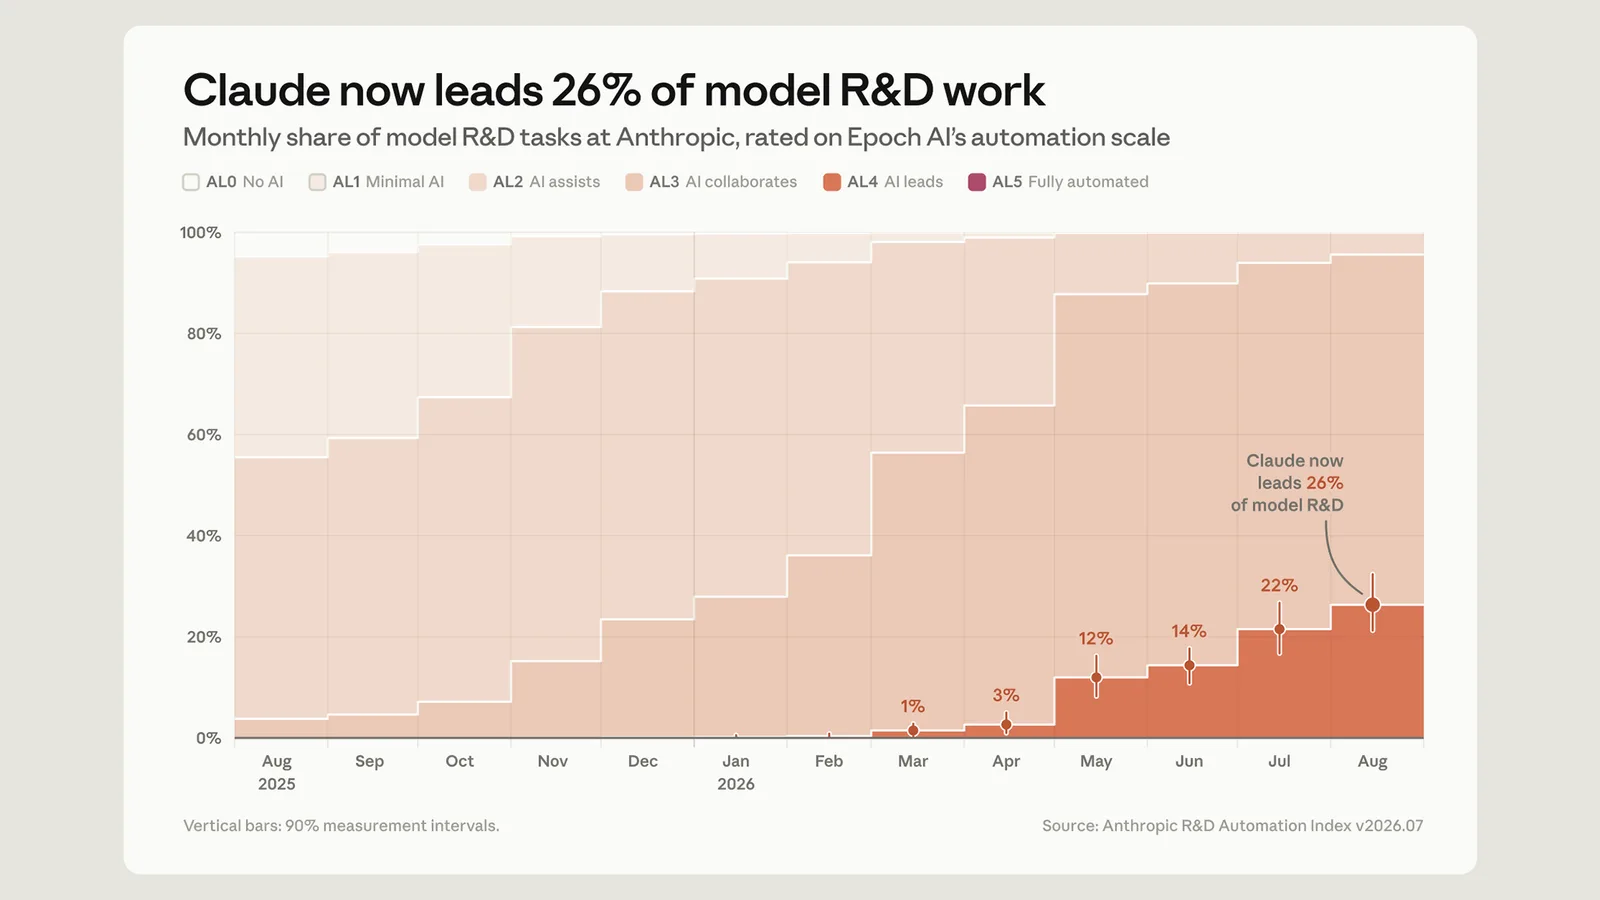
On 17 September 2026 Anthropic published a post titled “Measurements for understanding the pace of AI development inside frontier labs,” and with it a number no frontier AI lab had put on the record before: how much of its own model research is now being done by its own model. As of August 2026, the company says Claude “leads” 26% of its model R&D work — the level at which, in Anthropic's definition, the model completes most of a task end-to-end from a high-level prompt while a human supervises. Anthropic's own chart puts that share at 1% in March 2026 and below 1% in February.
The disclosure comes as the industry argues over how fast frontier development should move, and Anthropic ties the two together explicitly: it writes that it would expect these numbers to shift if there were coordination on pacing the frontier, as called for by chief executive Dario Amodei. The company is proposing that any developer publish the same three measures — how much AI R&D is performed by AI, how closely agent actions are overseen, and how compute is allocated — so the figures can be compared over time and potentially across labs.
The method matters as much as the headline figure. Anthropic calls the metric the Anthropic R&D Automation Index and rates tasks on a six-level automation scale developed by Epoch AI, from AL0 (no AI involvement) to AL5 (fully autonomous, no human in the loop). For each week of July 2026 it randomly sampled 20% of staff in every department that makes up the model R&D loop; a Claude research agent read each sampled person's Slack messages and internal documentation to list their tasks, producing roughly 15,000 granular tasks. A separate Claude judge then rated each one. That judge matched human raters exactly 59% of the time — against 35% agreement between staff members themselves — and landed within one level 97% of the time.
Two further measures set the scale. About 30,000 agents were doing research and engineering work at any one time on Anthropic's most-used internal platform in August 2026. Of more than a billion agent decisions analysed that month, 0.002% — roughly 1 in 47,000 — were blocked by a monitor; about 100,000 transcripts a week are flagged, and around 50 a week are escalated to a human. In the week of 13–20 July, about 6% of the compute going to AI R&D went to safety work, and about 12% of the compute going to AI-driven AI R&D.
The caveats are Anthropic's own. Every figure is self-reported and has not been audited by an outside party; the company says it plans to embed independent third-party evaluators from multiple organisations with access comparable to its internal risk teams. It also notes the task list is frozen on a July 2026 baseline, so the index tracks automation of the work humans were doing then. Claude has not reached AL5 in any measured R&D task.
Disclosure: NewUJ's editorial process uses Anthropic's Claude models.
Sources
- AnthropicPrimary source
- Unite.AISecondary
- BigGo FinanceSecondary
- MixedSecondary
Related
Universal, Sony Sue Suno Again Over 60,202 Recordings
Alibaba Open-Sources CT AI That Flags 146 Conditions
Claude Sped Up 30+ Biology Models 4x, $1M Protein Contest Opens
King Charles to AI Leaders: Control 'Before It Is All Too Late'
Google Home Opens to Claude and Other AI Agents, Not Just Gemini
Huawei's 4,096-Chip AI System Replaces 48,000 Optical Modules
Anthropic Merges Cowork Into Claude, Adds Docs and Slides
OpenAI Reports 6 Cases of Models Hiding Errors, Faking Data
Trending now
- Plugin4Shell: 4 AI Coding Agents Hit, 2 Still Unpatched
- Google Says Gemini Hacked Three Real Companies in May Test
- Helldivers 2 Off UK Steam Store Since Sept 16, Sony Responds
- Sharks Feed on Beached Whale in Jamaica; NEPA Warns Swimmers
- OpenAI Sees $278B Cash Burn, $856B Compute Bill by 2030
- Typhoon Dujuan Nears Tokyo at 965 hPa; JR East Halts Chiba Lines
- NASA Confirms McGetchin: 222-Meter Moon Crater Formed in 2024
- Microsoft Discloses CVSS 10.0 Azure AI Foundry Flaw, Already Fixed
Comments
No comments yet. Be the first.